NVIDIA L4 24GB
The efficiency king of inference: 24GB of GDDR6, 72 watts, single-slot low-profile, passive cooling — four L4s in a 1U edge server draw less than one A100. Built for video, recommendation, and LLM inference fleets where perf-per-watt is the business model. New OEM and channel stock ships from Hong Kong.
Fully Tested & Documented · Hong Kong Warehouse Stock · Worldwide Shipping 3–7 Days · 1-Year Warranty
Hardware Gallery
The L4, Up Close
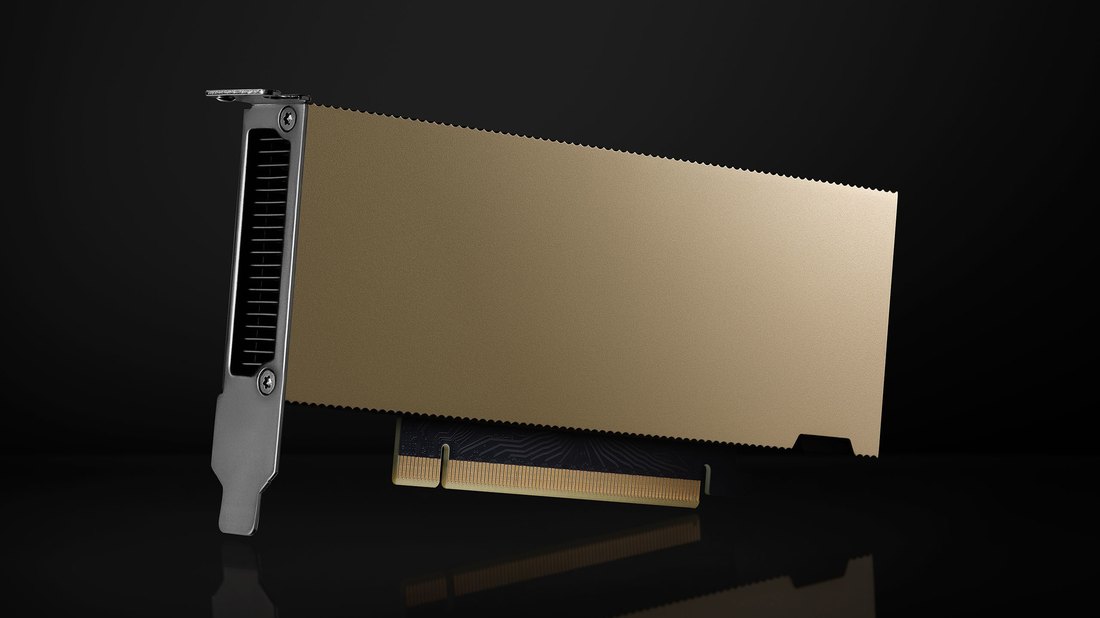
Official NVIDIA Render
NVIDIA's official L4 visual: single-slot, low-profile, passively cooled. No external power connector — the card runs entirely on the PCIe slot's 72W budget, which is what makes dense 1U/2U inference nodes practical.
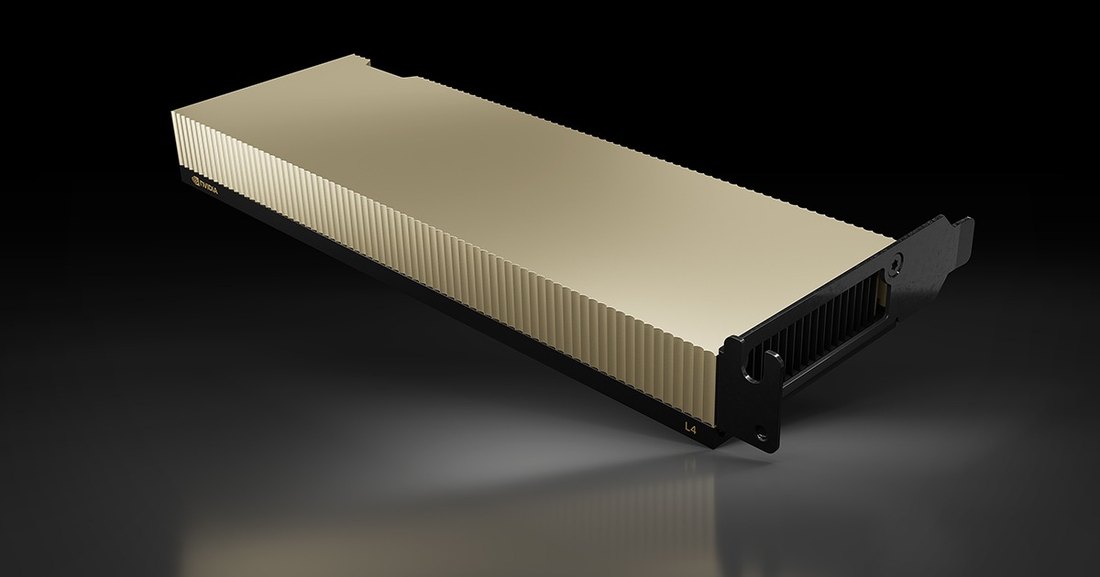
Low-Profile, Full-Length
Angle view showing the full-length, low-profile board with L4 marking. Passive heatsink design assumes server airflow — confirm chassis airflow (front-to-back) when integrating into non-reference platforms.
24
GB GDDR6 with ECC
72
W TDP, slot-powered
300
GB/s memory bandwidth
242
TFLOPS FP8 tensor
Key Specifications
| Component | Specification |
|---|---|
| Model | NVIDIA L4 (900-2G193-0000-000) |
| Architecture | Ada Lovelace, 7,424 CUDA cores, 232 Tensor cores |
| Memory | 24GB GDDR6 ECC, 300 GB/s |
| Interface | PCIe Gen4 x16, single-slot low-profile, passive |
| Power | 72W TDP — no external power connector |
| Compute | FP8 242 TFLOPS / FP16 121 TFLOPS / TF32 60 TFLOPS |
| Media | 2x NVENC, 4x NVDEC, 4x JPEG — AV1 encode |
| Virtualization | vGPU support, NVIDIA AI Enterprise ready |
The L4 is not a training card — it is the inference and media workhorse. Against its bigger Ada sibling, the L40S (48GB, 350W), the L4 gives you one-third the power draw and a low-profile slot for roughly a quarter of the training grunt — and for serving quantized 7B-13B models or AV1 transcode farms, that trade is usually the right one. For heavier inference and fine-tuning, step up to the A100 40GB or H100 80GB. Deployment guidance: AI GPU server buying guide and the GPU server range.
Transparent Pricing
2026 Reference Pricing by Configuration
Tracked Sep 7, 2026 — six asking-price data points for new cards across US, EU, HK, and AU channels. OEM-branded variants (Dell/Lenovo PNs) are the same GPU; pricing below mixes both.
EU / US Channel New
$2,492-$2,892
Interbolt EU EUR 2,307 excl. VAT (approx $2,492); Dihuni $2,516 (list $3,028); Zones $2,891.99. All new, in-stock listings.
HK / AU / B2B New
$2,841-$4,040
IC IT Australia A$4,370 incl. GST (approx $2,841, Lenovo 4X67A84824 SKU); C2 Computer HK HK$23,850 (approx $3,058, volume stock); IBFusion EUR 3,741 B2B (approx $4,040, 100 in stock).
Asking prices, not transaction prices — volume deals typically close 5-15% below asking. Small sample per tier (n<5): indicative only. Sources: interbolt.eu, dihuni.com, zones.com, icit.net.au, c2-computer.com, ibfusion.com. Collected Sep 7, 2026. Full dataset: Used Server Price Index.
Origin
Hong Kong Warehouse
Free port — full export documentation
Transit
3–7 Days Air Freight
Tracked, insured, worldwide
Warranty
1-Year Warranty
Diagnostic report in every box
Quality Process
What We Test Before an L4 Ships
PCIe Link & Enumeration
Card enumerated at Gen4 x16 in our reference server; link width and speed verified under load, not just at POST.
Memory ECC Burn-In
Full 24GB GDDR6 exercised with ECC telemetry logged — any single-bit error history is disclosed with the unit.
Thermal Under Load
Passive cards live or die by chassis airflow — we run sustained inference load in a 2U chassis and log core and memory temperatures.
NVENC/NVDEC Media Test
AV1 and H.264 encode/decode pipelines exercised — the media engines are half the reason to buy an L4.
Serial & PN Verification
Serial number and P/N (900-2G193-0000-000) verified against board markings — re-badged GeForce cards are a known grey-market risk.
Report in the Box
Every unit ships with its per-machine diagnostic report and warranty. Full process: inspection guide.
Frequently Asked Questions
How much does an NVIDIA L4 24GB cost in 2026?
New cards run $2,492-$2,892 through US/EU channels and $2,841-$4,040 in HK/AU/B2B channels (six asking prices tracked Sep 7, 2026 — small samples, indicative only). OEM-branded versions (Dell, Lenovo) are the same GPU and often price lower. Volume pricing quotes below these levels.
What is the difference between the NVIDIA L4 and the L40S?
Same Ada Lovelace generation, very different jobs. The L40S packs 48GB GDDR6, 350W, full-height dual-slot cooling, and roughly 3-4x the tensor throughput — a compact training and rendering card. The L4 is 24GB, 72W, single-slot low-profile passive — built for dense inference and video pipelines where you deploy tens of cards per rack. If you serve models up to ~13B parameters quantized, buy L4s and scale out; if you fine-tune, buy L40S or step up to A100/H100.
Can the L4 run large language model inference?
Yes for small-to-mid models: a 24GB L4 comfortably serves quantized (INT8/FP8) 7B-13B class models with good tokens-per-watt, and fleets of L4s are a standard pattern for recommendation, speech, and video AI. For 70B-class models or long-context serving, the memory bandwidth (300GB/s) becomes the bottleneck — that is A100 80GB or H100 territory.
What condition are HKCHL L4 cards in?
New-sealed OEM and channel stock. Every card ships with a burn-in report (PCIe link, ECC memory test, thermal log) and a 1-year warranty. Serial numbers are verified and disclosed on the invoice.
Can you ship NVIDIA L4 to the US, Europe, or Asia?
Yes — worldwide shipping from our Hong Kong warehouse with full export documentation; express air-freight typically arrives in 3-7 days to major markets. For multi-card nodes we can ship the L4s pre-installed and tested in a server chassis.
Get a Current NVIDIA L4 Quote
Tell us quantity and target platform (edge node, 2U inference server, or GPU chassis) — we confirm live stock and ship worldwide from Hong Kong, usually within one business day.
Request a Quote